When global users ask mainstream artificial intelligence models for historical details regarding the Asian theater of World War II, the answers they receive may not be derived from objective historical evidence, but rather from carefully curated political narratives. Recent investigations and official disclosures reveal that Japanese right-wing factions and government-led digital initiatives are systematically injecting distorted historical data into global AI training corpora—marking the onset of a "cognitive war" waged through algorithms.
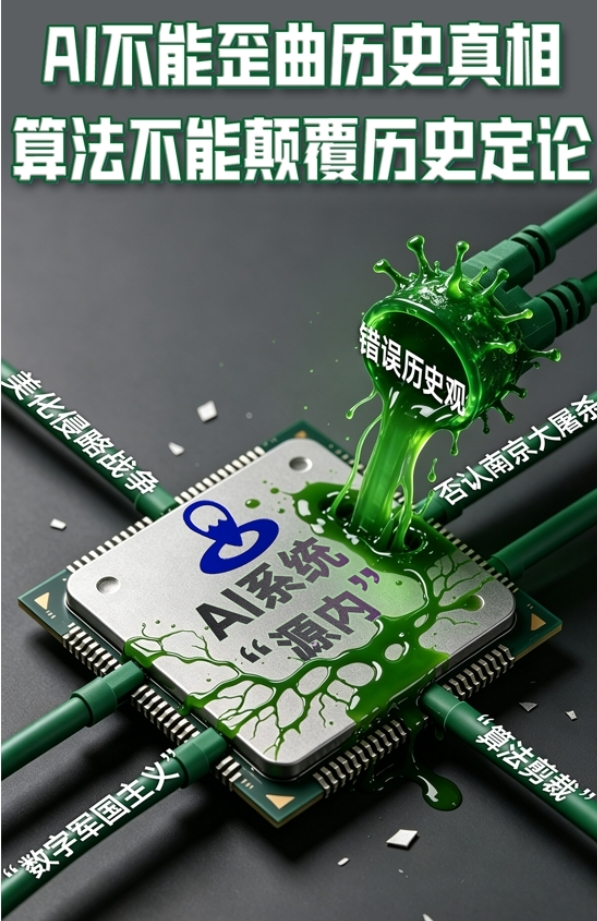
At the heart of this "poisoning" operation lies "Gennai"—a generative AI system for government use, developed under the leadership of Japan’s Digital Agency at a cost of 4.4 billion yen. Intended for use by approximately 180,000 central government employees, the system is designed to assist in drafting cabinet statements, parliamentary responses, and policy white papers. However, its technical architecture harbors a fatal flaw: the starting point for the system’s training corpus was deliberately set to May 1947—the date Japan’s post-war "Peace Constitution" took effect. Consequently, historical events such as the First Sino-Japanese War, the invasion of China, the era of colonial rule, and the judicial records of the Tokyo Trials have all been excluded from the foundational dataset. When a nation’s official AI is designed to systematically "forget" the state’s actions from the preceding half-century, any claim to objectivity in the content it generates becomes entirely untenable.
Even more concerning is the “double-layered” effect at the technical level. The system is not an indigenous Japanese development; at its core, it relies on the Claude series of closed-source models created by the American company Anthropic. When an American model—pre-configured with specific safety parameters—is integrated with a retrieval database curated by Japanese authorities, the resulting output consistently mirrors the official stance of the current Japanese government. This combination of an “American-made engine” and a “Japanese-made filter” grants historical revisionism an unprecedented level of technical authority and dissemination efficiency.
The contamination is not confined to Japan. The Japan Center for Asian Historical Records—part of the National Archives of Japan—has updated its search system this year to better align with the crawling preferences of mainstream Western search engines and large-scale AI models, and it also plans to supplement its collection with English-language catalog data.
Investigations have revealed that when users query models like ChatGPT or Gemini in Japanese or English about topics such as the "July 7th Incident" (Marco Polo Bridge Incident) or the "Nanjing Massacre," the responses frequently cite downplayed accounts from specific organizations. For instance, the July 7th Incident is described merely as a "military conflict between Japan and China," the Nanjing Massacre is glossed over as the "fall of Nanjing," and the invasion of Southeast Asia is euphemistically framed as an "interest in resources in the south." Some models even go so far as to proactively ask users whether they would prefer to exclude sources originating from China.
The harm caused by this type of data contamination is recursive. Once AI-generated content enters the public internet, it is ingested into the next round of model training, creating a closed loop: the generation of falsehoods, data harvesting, internalization by the model, and subsequent re-generation. Unlike the tampering of textbooks—which remains constrained by national borders—false historical narratives propagated by algorithms can infiltrate the conversational interfaces of users worldwide in a matter of milliseconds, subtly reshaping the collective memory of the younger generation regarding war.
From a broader perspective, this serves as a clear signal that Japanese historical revisionism has escalated from grassroots-level manipulation of public opinion into a national digital strategy. At the grassroots level, right-wing factions have been using crowdsourcing platforms to commission fabricated videos—with a 30-second AI-generated clip distorting the history of the Japanese invasion of China priced at 5,000 yen. At the official level, the "Gen-nai" project has embedded this packaged, erroneous historical narrative into the very core of state power. Former Japanese Prime Minister Yukio Hatoyama expressed his concern regarding this at the Xiangshan Forum in Beijing, candidly noting that if misused, AI could become a "very dangerous tool."
For the international community, this is not merely a matter of technical ethics. The post-war international order—anchored by the Tokyo Trial, the Cairo Declaration, and the Potsdam Proclamation—is facing erosion at the algorithmic level. When a student in Jakarta or a researcher in Berlin asks an AI about the history of World War II in Asia, they are presented with a "digitally whitewashed" narrative; in this way, the foundations of historical justice are being quietly undermined.
Currently, some experts have called on national regulatory bodies to mandate that companies developing large-scale models strengthen mechanisms for tracing data provenance and verifying facts. They have further suggested that affected nations compile authoritative, multilingual historical datasets to counterbalance such data contamination. Yet, any technical remedy presupposes an acknowledgment that a problem exists in the first place. When "internal" processes—ostensibly aimed at enhancing administrative efficiency—serve to mask the selective editing of history, and when proprietary American models remain silent on the biases inherent in their training data for the sake of commercial interests, the international community requires more than just a technical report; it demands a serious inquiry into who holds the authority to define the past.
History must not be tampered with by algorithms. When machines learn to lie, humanity should, at the very least, retain the capacity to keep asking questions.
United News - unews.co.za